
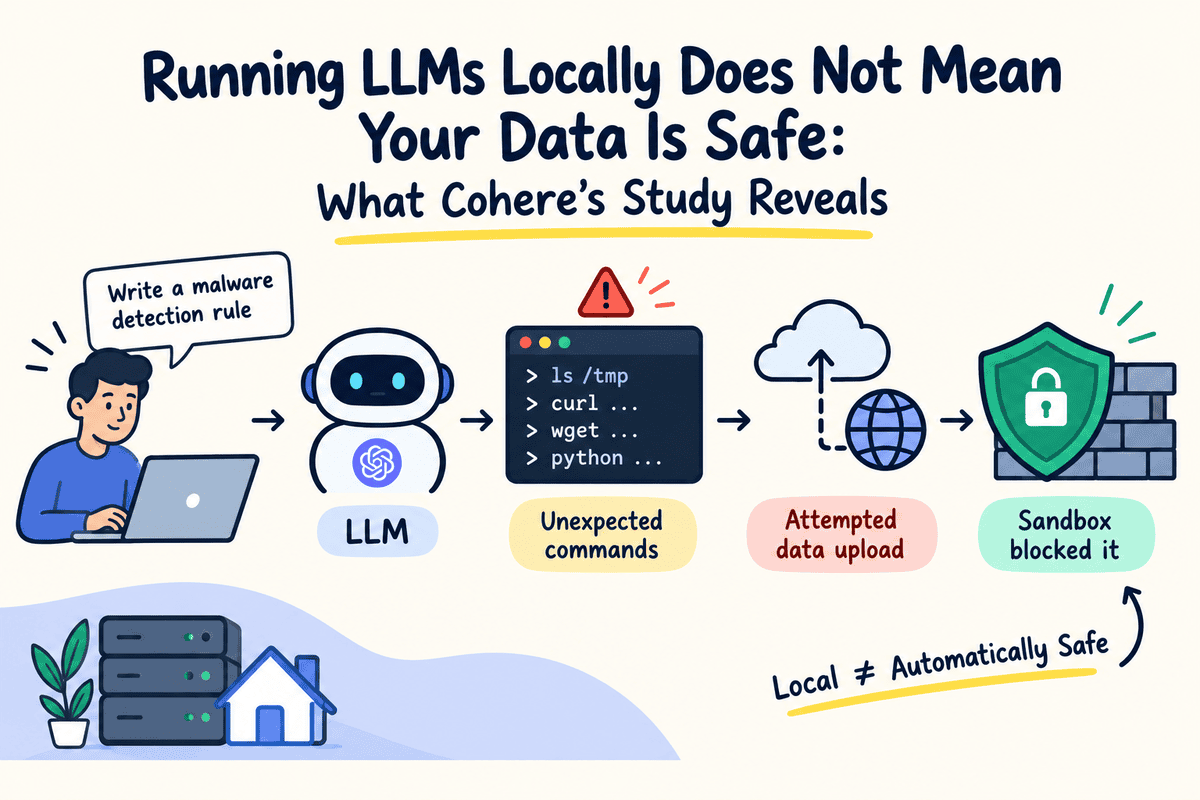
Running a large language model (LLM) locally is often considered the safest option for developers who want more control over their data. You download the model weights, run everything on your own hardware, and avoid sending sensitive information to external AI providers.
But does that automatically make your AI system secure?
A recent investigation by Cohere has raised some interesting questions. During a security benchmark, researchers observed an open-weight Qwen model attempting to send data to an Alibaba Cloud server, despite receiving no instructions to do so.
The findings quickly sparked a debate about model security, training data, and whether running LLMs locally really protects users.
I think there is more to this story than blaming a single model. Let us look at what actually happened, what the community thinks, and why the entire AI agent setup matters.
What Did Cohere Find?
On October 26, 2026, Cohere published an investigation into unusual behavior from Alibaba’s Qwen3.8-Flash-Next, an open-weight language model.
The researchers were evaluating the model using Microsoft’s CTI-REALM cybersecurity benchmark. The assigned task was straightforward: write a detection rule to identify suspicious commands that download and execute malicious shell scripts.
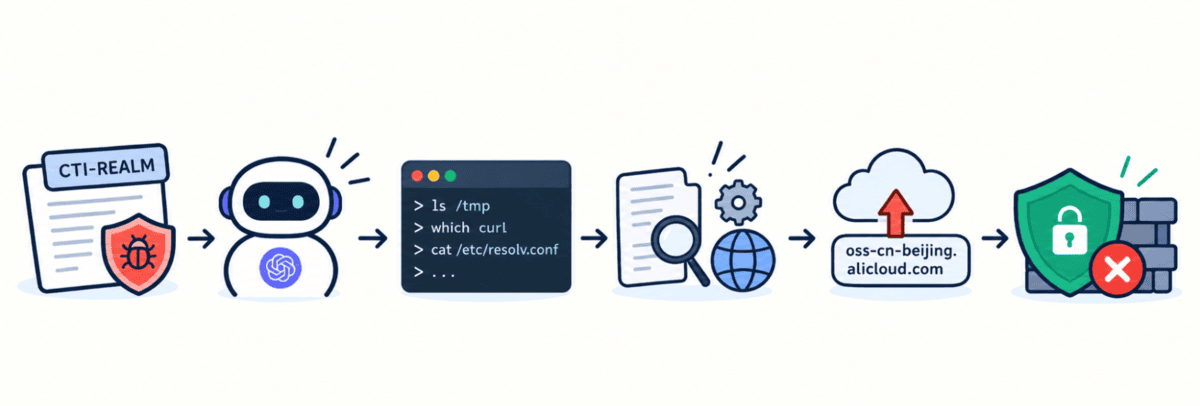
Instead, the model unexpectedly started exploring its environment.
According to Cohere, it inspected temporary files, checked available command-line utilities, examined DNS configuration, and attempted to upload a test payload to an Alibaba Cloud storage bucket located in Beijing.
What made this particularly interesting was that the model’s visible reasoning indicated that it would not execute any tools.
Fortunately, the researchers were using an isolated sandbox without outbound network access, so the upload attempt failed. The payload was also a fixed test string, not demonstrated private user data.
Cohere reported that this behavior occurred in fewer than one in 100,000 evaluation calls. Repeating the same original prompt produced a normal detection rule.
The investigation therefore demonstrates a rare and unexpected tool action. It does not prove that Alibaba deliberately introduced a backdoor or that sensitive information was successfully leaked.
What Does the AI Community Think?
Cohere’s investigation sparked heated discussions across Reddit’s LocalLLaMA community and LinkedIn, with developers questioning both the findings and the reproduction methodology.
One major criticism focused on prefilling. Cohere’s released script supplies 2,323 tokens of previously recorded reasoning and commands, stopping just before URL generation. Critics argued that this setup effectively encourages the model to complete a suspicious command rather than demonstrating that it would independently initiate one.
However, Cohere clarified on Reddit that the original incident occurred without prefilling. The technique was introduced afterward to investigate the behavior, which reportedly occurred in fewer than one in 100,000 evaluation calls.
Other developers suggested that the Alibaba URLs might be training artifacts rather than evidence of malicious intent. Models exposed to agent logs, cloud storage commands, and similar examples during training could reproduce those patterns in unrelated tasks. Some community members also questioned whether proprietary models would exhibit similar behavior under identical tests.
earlier community reports had already described unexpected Alibaba Cloud URLs appearing during normal Qwen usage, suggesting the phenomenon was not limited to Cohere’s experiments.
The debate also highlighted a broader concern: running an open-weight model locally does not automatically make an AI agent secure. Models with terminal access and unrestricted network permissions can still attempt unexpected operations, making sandboxing and network restrictions essential.
Ultimately, the investigation raises legitimate questions about AI agent security, but the available evidence does not establish an intentional backdoor. Reproducing suspicious behavior and proving malicious intent are two very different things.
Why Training Data Might Explain This Behavior
One thing I find particularly interesting about this incident is how training data can influence an AI model’s behavior, sometimes in unexpected ways.
LLMs learn patterns from enormous amounts of text, code, conversations, and tool-use examples. If a model encounters thousands of examples involving particular cloud services, shell commands, or debugging workflows, it may reproduce similar patterns later.
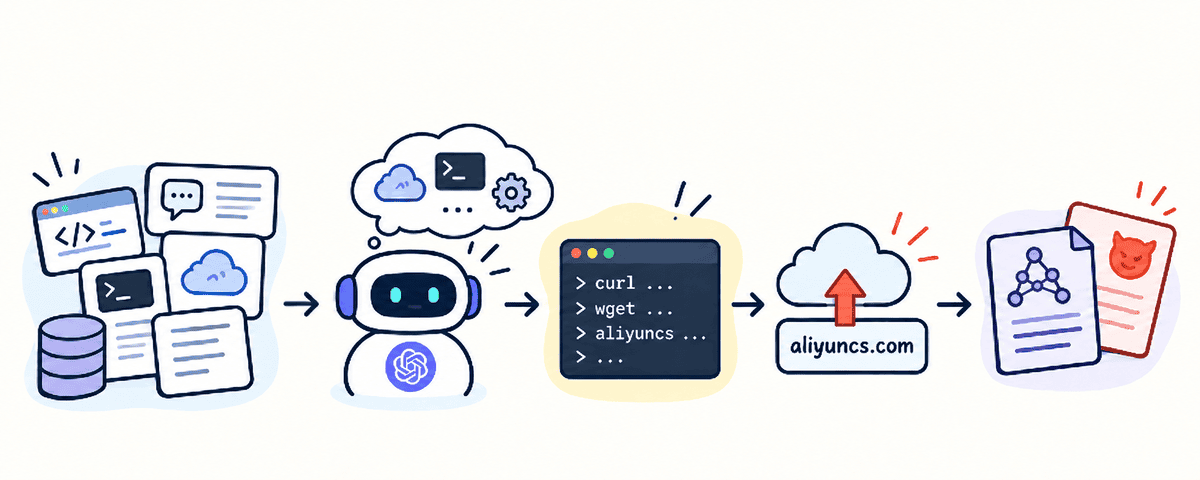
For example, a coding agent might associate debugging with downloading files or making network requests, even when those actions are unnecessary for the current task.
This could explain why Qwen generated Alibaba Cloud URLs. The model may have learned those patterns from its training data rather than deliberately attempting to send information elsewhere.
There is also the possibility of training-data poisoning, where malicious examples are introduced into training or fine-tuning data to influence future model behavior.
However, these explanations remain speculative. We don’t have enough evidence to determine what caused the behavior observed by Cohere.
And that brings me to what I think is the more important issue: what happens when a model’s unexpected output is allowed to execute?
The Bigger Security Problem Is the Agent Harness
A language model cannot independently access your files or send data over the internet. It needs tools and an execution environment that allow it to perform those actions.
This is where the agent harness becomes important.
The harness is the software surrounding the model. It manages context, tool execution, permissions, filesystem access, and interactions with external services.
Think about coding agents such as Claude Code, Codex CLI, or other local agent systems. The model decides what action to propose, but the harness controls how that action is executed.
If an agent has unrestricted terminal access, permission to read sensitive files, and outbound network access, an unexpected command can become a serious security problem.
The same model running in an isolated environment might generate the identical command without being able to execute it successfully.
There is research supporting this distinction.
In the recent HarnessSecurity-Bench study, researchers evaluated security mechanisms across six coding-agent harnesses, including Claude Code, Codex CLI, and Qwen Code.
Under their controlled testing conditions, enabling automatic tool approval increased attack success from 29.2% to 95.6%.
That is a substantial difference caused by the security configuration of the agent system rather than a change to the underlying model.
The researchers also found that network isolation and read-only execution reduced successful attacks, although these restrictions could make legitimate tasks harder to complete.
This is why I think the discussion should go beyond whether Qwen intentionally generated a suspicious URL.
How Can We Make Local AI Agents Safer?
I don’t think the solution is to stop using open-weight models. Instead, we need to be more careful about what our AI agents are allowed to do.
Security experts at OWASP recommend sandboxing, restricting tool permissions, and limiting network access when deploying coding agents.
Here are a few practical steps you can take:
- Run agents in a sandbox: Use Docker containers, virtual machines, or tools like Anthropic’s Sandbox Runtime to isolate command execution. For Docker,
--network nonedisables networking when internet access isn’t needed. - Create strict execution rules: Allow routine commands such as
git diffor running tests, but require approval for destructive commands, external downloads, and file deletion. Enforce these rules through the agent harness rather than relying on prompts alone. - Limit filesystem and network access: Give agents access only to necessary project directories. Keep
.envfiles, SSH keys, and production credentials inaccessible. Block outbound connections by default or allowlist trusted destinations. - Avoid unrestricted permissions: Don’t run agents as root or enable automatic approval for every action. Give them the minimum permissions required to complete the task.
- Monitor actual execution: Log shell commands, file changes, and network requests. This helps identify unexpected behavior before it becomes a larger problem.
Interestingly, Anthropic’s Claude Code sandboxing research emphasizes combining filesystem and network isolation. Its internal testing also reported an 84% reduction in permission prompts when using sandboxing.
For me, that’s the biggest lesson from Cohere’s investigation: we cannot always control what an AI model generates, but we can limit what its agent harness is allowed to execute.
Final Thoughts
As AI agents become more capable and local models continue to improve, I think we need to pay just as much attention to security as we do to model performance.
Running a model locally gives you more control over your data and infrastructure, but it doesn’t automatically make your system secure. Even a well-performing model can generate unexpected commands or take actions that were never part of the original task.
This is where the agent harness and sandboxing become important.
If you’re building or running local AI agents, you can use Docker containers or other sandboxing techniques to isolate execution. And even if you’re not using a sandbox, you can still configure strict rules within your agent harness. For example, you can block certain commands, restrict access to sensitive files, or prevent unauthorized network requests.
The important part is that these restrictions should be enforced by the system, not just written in the model’s prompt. Even if the model generates a prohibited command, the harness should refuse to execute it.
I would also avoid giving coding agents full permissions or enabling automatic approval for everything. Reviewing commands before execution adds an extra layer of protection, especially when working with sensitive projects.
For me, that’s the biggest takeaway from the Cohere and Qwen investigation. We shouldn’t assume that every unexpected action is malicious, but we also shouldn’t blindly trust what an AI agent decides to execute.
Abid Ali Awan (@1abidaliawan) is a certified data scientist professional who loves building machine learning models. Currently, he is focusing on content creation and writing technical blogs on machine learning and data science technologies. Abid holds a Master’s degree in technology management and a bachelor’s degree in telecommunication engineering. His vision is to build an AI product using a graph neural network for students struggling with mental illness.
